
AI-101 · Lesson 2 of 5 · 31 min
A short history of AI
Artificial intelligence is younger than most engineering fields but older than most people assume. Its history is a story of bold predictions, disappointments called "AI winters", quiet progress, and sudden breakthroughs when ideas, data and computing power finally came together. Knowing that history helps you judge today's claims: many current debates, about whether machines can reason, whether bigger is better, and whether progress will stall, have been argued before.
This chapter follows AI from its founding in the 1950s through symbolic AI and expert systems, the long rise of neural networks, the deep learning revolution of the 2010s and the arrival of large language models. It closes with the people and institutions that shaped the field, including the remarkable role Canada has played.
The founding: 1950s
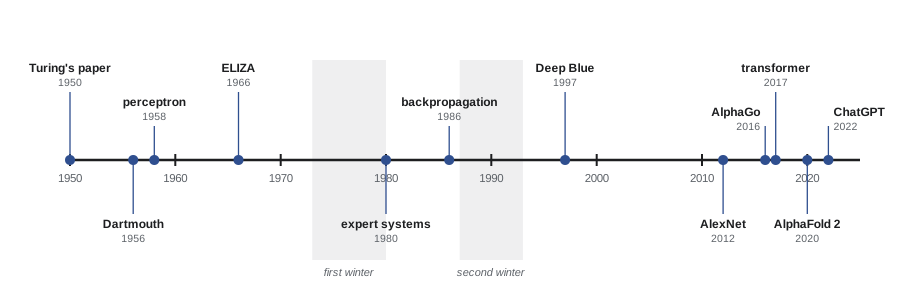
Turing's 1950 paper (Lesson 1) set out the question. The field got its name in 1956, at a summer workshop at Dartmouth College in New Hampshire organized by John McCarthy, Marvin Minsky, Nathaniel Rochester and Claude Shannon. Their proposal stated that "every aspect of learning or any other feature of intelligence can in principle be so precisely described that a machine can be made to simulate it", and suggested that a carefully selected group of scientists could make significant progress in one summer. They were wrong about the timescale by many decades, a pattern that would repeat.
The early years produced real achievements. Allen Newell and Herbert Simon's Logic Theorist proved theorems from Principia Mathematica. Arthur Samuel's checkers program at IBM learned to play better than its creator, and Samuel coined the term "machine learning" in 1959. In 1958 the psychologist Frank Rosenblatt built the perceptron, a single artificial neuron that learned to classify simple patterns by adjusting its weights (you will implement one in Lesson 3). The press predicted machines that would soon walk, talk and see.
Symbolic AI and the first winter
Through the 1960s, the dominant approach was symbolic: represent knowledge with logic and symbols, and solve problems by search. Programs solved algebra word problems, played games and manipulated blocks in simulated worlds. Joseph Weizenbaum's ELIZA (1966) imitated a psychotherapist with simple pattern-matching rules, and some users became emotionally attached to it, which disturbed Weizenbaum.
The trouble came with scale. Methods that worked on toy problems collapsed on real ones because the number of possibilities grew exponentially (the "combinatorial explosion"), and because real-world knowledge was far larger and messier than anyone had estimated. In 1969 Minsky and Seymour Papert's book Perceptrons showed that a single-layer perceptron cannot learn some simple functions, such as exclusive-or (XOR), and interest in neural networks faded. In 1973 the Lighthill Report to the UK government judged that AI had failed to deliver on its promises, and British funding was cut sharply; American funding agencies also pulled back. The first AI winter lasted through much of the 1970s.
Worked problem
Why search explodes
A game has about 35 legal moves per position (roughly the average in chess). How many positions must a program examine to look ahead 4 moves (plies) and 10 plies, without any shortcuts? At a million positions per second, how long does each take?
Show solution
- 4 plies: \(35^4 = 1.5 \times 10^6\) positions, about 1.5 seconds.
- 10 plies: \(35^{10} = 2.8 \times 10^{15}\) positions, about \(2.8 \times 10^9\) seconds, roughly 87 years.
Answer: About 1.5 seconds versus about 87 years. Each extra ply multiplies the work by 35. Practical game programs survive only by pruning most branches (alpha-beta search) and evaluating positions cleverly
Expert systems and the second winter
AI revived in the 1980s with expert systems, programs that captured a human expert's knowledge as hundreds or thousands of if-then rules. MYCIN, developed at Stanford in the 1970s, recommended antibiotics for blood infections about as well as specialists in tests. Digital Equipment Corporation's XCON configured computer orders and was reported to save the company millions of dollars a year. Companies built AI departments, and specialized "Lisp machines" were sold to run AI software.
Expert systems proved expensive to build and brittle to maintain: every new situation needed new rules, the rules interacted in unexpected ways, and the systems could not learn or handle cases their builders had not anticipated. When cheaper general-purpose workstations made Lisp machines obsolete and the promised returns did not arrive, the market collapsed in the late 1980s, starting the second AI winter. For years afterwards, many researchers avoided the term "AI" and described their work as machine learning, pattern recognition or informatics instead.
Quiet progress: statistics, learning and backpropagation
While "AI" was out of fashion, the foundations of today's systems were being laid.
- In 1986 David Rumelhart, Geoffrey Hinton and Ronald Williams popularized backpropagation, an efficient way to train neural networks with hidden layers. Multi-layer networks can learn XOR and much more, answering Minsky and Papert's objection.
- In 1989 Yann LeCun and colleagues at Bell Labs trained convolutional neural networks to read handwritten digits; versions of this system read a large share of cheques in the United States in the 1990s.
- Probabilistic methods, such as Bayesian networks and hidden Markov models, gave AI a rigorous way to reason under uncertainty and powered speech recognition.
- Richard Sutton and Andrew Barto developed reinforcement learning, in which an agent learns from rewards and penalties; their textbook appeared in 1998.
- Support vector machines and decision tree ensembles became the workhorses of practical machine learning in the 1990s and 2000s.
Milestones reached the public too. In 1997 IBM's Deep Blue defeated world chess champion Garry Kasparov in a six-game match, mainly through massive search on custom hardware. In 2011 IBM's Watson won the quiz show Jeopardy! against two human champions.
The deep learning revolution: 2012 onward
Neural networks had been around for decades, but three things changed in the late 2000s: huge labelled datasets (ImageNet, built by Fei-Fei Li's team, contained more than 14 million labelled images), graphics processing units (GPUs) that could train networks many times faster than ordinary processors, and better training techniques.
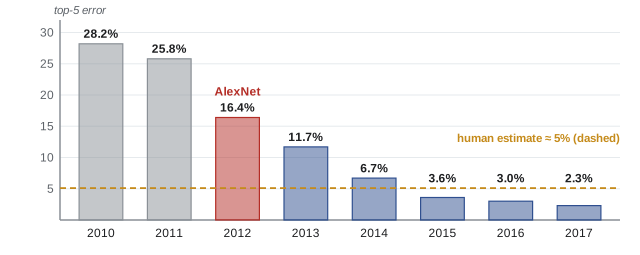
In 2012 a network called AlexNet, built at the University of Toronto by Alex Krizhevsky, Ilya Sutskever and Geoffrey Hinton, won the ImageNet image-classification challenge with a top-5 error rate of about 16% (15.3% for its best version), against about 26% for the next-best entry. (Top-5 error counts an image as wrong if the correct label is not among the model's five best guesses.) Within a few years almost every entry was a deep network, and by 2015 the best systems made fewer errors on this benchmark than a human annotator who had trained for the task.
Worked problem
How big was the AlexNet jump?
The best top-5 error fell from 25.8% (2011) to 16.4% (2012), then to 3.6% by 2015. Compare the relative improvement in 2012 with the average yearly relative improvement over the previous year (2010 to 2011, from 28.2%).
Show solution
- 2010 to 2011: (28.2 − 25.8)/28.2 = 8.5% fewer errors.
- 2011 to 2012: (25.8 − 16.4)/25.8 = 36% fewer errors in a single year.
- 2012 to 2015: errors fell from 16.4% to 3.6%, a factor of 4.6 in three years.
Answer: A 36% reduction in one year, against about 8.5% the year before. That discontinuity convinced most of the computer vision community to switch to deep learning almost overnight
Deep learning then swept through speech recognition, machine translation and game playing. In 2016 DeepMind's AlphaGo defeated Lee Sedol, one of the world's strongest Go players, four games to one. Go had been considered a decade or more away because its search space is vastly larger than chess's; AlphaGo combined deep networks, reinforcement learning and search. In 2020 DeepMind's AlphaFold 2 predicted protein structures with accuracy comparable to laboratory methods, solving a 50-year-old problem in biology.
Transformers and large language models
In 2017 a team at Google published "Attention Is All You Need", introducing the transformer, a neural network architecture built around a mechanism called attention, which lets every word in a sequence draw information directly from every other word. Transformers train efficiently on GPUs and scale well, and they became the basis of nearly all modern language models (AI-340 covers them in detail).
Researchers found that language models trained simply to predict the next word in vast amounts of text kept improving as they were made larger and trained on more data and compute, following surprisingly regular scaling laws. OpenAI's GPT-3 (2020), with 175 billion parameters, could write essays and answer questions from a few examples in its prompt. When OpenAI released ChatGPT on November 30, 2022, a version trained to follow instructions and hold conversations, it became one of the fastest-adopted consumer products in history. Since then, many companies and research groups have released models that work with text, images, audio and video, write and run code, and carry out multi-step tasks as agents.
The scale of training has grown extraordinarily fast. Epoch AI, a research group that tracks these trends, estimates that the compute used to train frontier language models has grown about 5 times per year since 2020, and training costs about 3.5 times per year.
Worked problem
What 5× per year means
If training compute grows 5× per year, by how much does it grow in 4 years? How long does it take to double?
Show solution
- In 4 years: \(5^4 = 625\) times.
- Doubling time: solve \(5^t = 2\): \(t = \ln 2/\ln 5 = 0.43\) years, about 5.2 months.
Answer: About 625 times in four years, doubling roughly every 5 months. Compare Moore's law for transistor counts, which doubled about every two years. Growth this fast is why AI has become a major driver of data centre and electricity demand (DCE-200)
Recognition: the field comes of age
The pioneers of deep learning, once on the fringe, received the field's highest honours. Yoshua Bengio, Geoffrey Hinton and Yann LeCun shared the 2018 A.M. Turing Award, often called the Nobel Prize of computing. In 2024 the Nobel Prize in Physics went to John Hopfield and Geoffrey Hinton for foundational discoveries that enable machine learning with neural networks, and the Nobel Prize in Chemistry was shared by David Baker, and by Demis Hassabis and John Jumper of DeepMind for AlphaFold. Andrew Barto and Richard Sutton received the 2024 Turing Award, announced in 2025, for reinforcement learning.
Several of the same pioneers have also become prominent voices warning about the risks of advanced AI, a debate taken up in Lesson 5 and AI-430.
Canada's role
Canada had an outsized role in the deep learning story, largely because of patient public funding of research that was unfashionable elsewhere. The Canadian Institute for Advanced Research (CIFAR) funded a program on neural computation from 2004, led by Geoffrey Hinton at the University of Toronto, which kept a small international community of neural network researchers working together through the years when the approach was out of favour. Yoshua Bengio built a leading group at the Université de Montréal, and Richard Sutton, one of the founders of reinforcement learning, moved to the University of Alberta in 2003.
In 2017 Canada became the first country to launch a national AI strategy, the Pan-Canadian Artificial Intelligence Strategy, administered by CIFAR. It funds three national AI institutes: Amii (the Alberta Machine Intelligence Institute) in Edmonton, Mila in Montréal and the Vector Institute in Toronto. Canada is also home to the Canadian AI Safety Institute, launched in 2024, and in June 2026 the federal government launched a new national strategy, "AI for All", which Lesson 5 describes.
Talent flowed in both directions. Many Canadian-trained researchers went on to found or lead major AI companies and laboratories in the United States and Europe, including OpenAI co-founder Ilya Sutskever, a former student of Hinton's. Keeping talent and building companies at home is a recurring theme of Canadian AI policy.
Lessons from history
A few patterns recur and are worth carrying forward:
- Predictions about timing have often been wrong in both directions. Early researchers expected human-level AI within a generation; later skeptics said Go was decades away. Treat confident timelines with caution.
- Hype cycles are real. Overpromising led to two funding collapses. Claims should be backed by careful measurement.
- Ideas often wait for data and compute. Neural networks and backpropagation existed for decades before GPUs and large datasets made them practical.
- General methods that scale with computation have tended to beat hand-crafted knowledge over time. Richard Sutton called this "the bitter lesson" in a 2019 essay. It remains debated, but it describes the last decade well.
- Each wave raised new social questions, from Weizenbaum's unease about ELIZA to today's debates on safety, jobs and power.
Common mistakes
MistakeThinking neural networks were invented recently.
InsteadThe perceptron dates from 1958 and backpropagation was popularized in 1986. What changed around 2012 was data, GPUs and training techniques.
MistakeBelieving the first AI researchers were naive.
InsteadThey achieved real results; they underestimated the combinatorial explosion and the amount of knowledge real tasks need.
MistakeAssuming progress is steady.
InsteadAI has advanced in bursts, separated by winters when results fell short of promises.
MistakeTreating Deep Blue and AlphaGo as the same kind of system.
InsteadDeep Blue relied mostly on brute-force search with hand-tuned evaluation; AlphaGo combined learned deep networks, reinforcement learning and search.
Summary and key terms
- Turing (1950) posed the question; the 1956 Dartmouth workshop named the field. Early successes included theorem provers, checkers and the perceptron (1958).
- Symbolic AI hit the combinatorial explosion; Perceptrons (1969) and the Lighthill Report (1973) led to the first AI winter.
- Expert systems boomed in the 1980s but proved brittle, leading to the second winter in the late 1980s.
- Backpropagation (1986), convolutional networks, probabilistic methods and reinforcement learning laid the foundations; Deep Blue beat Kasparov in 1997.
- Data (ImageNet), GPUs and better techniques produced the deep learning breakthrough with AlexNet in 2012, then AlphaGo (2016) and AlphaFold 2 (2020).
- The transformer (2017) and scaling led to large language models; ChatGPT (November 2022) brought them to the public. Frontier training compute has grown about 5× per year since 2020.
- Turing Awards (2018, 2024) and Nobel Prizes (2024) recognized the field's pioneers.
- Canada, through CIFAR, Hinton, Bengio and Sutton, played a central role, and launched the first national AI strategy in 2017 with Amii, Mila and Vector.
- Dartmouth workshop
- The 1956 summer meeting at which the term "artificial intelligence" was adopted for the new field.
- Perceptron
- Rosenblatt's 1958 single artificial neuron that learns to classify inputs by adjusting weights.
- AI winter
- A period of reduced funding and interest after AI failed to meet expectations.
- Combinatorial explosion
- The exponential growth in the number of possibilities as a problem gets larger.
- Expert system
- A program that encodes a human expert's knowledge as rules to solve problems in a narrow domain.
- Backpropagation
- An algorithm for computing the gradients needed to train multi-layer neural networks.
- ImageNet
- A dataset of more than 14 million labelled images whose annual challenge drove progress in computer vision.
- GPU
- Graphics processing unit: a processor with thousands of parallel cores, now the main hardware for training neural networks.
- Transformer
- The 2017 neural network architecture based on attention that underlies modern language models.
- Scaling laws
- Regular relationships between a model's performance and its size, training data and compute.
- Bitter lesson
- Sutton's observation that general methods that use more computation tend to beat methods built on human knowledge.
Practice problems
Work each problem on paper first, then reveal the answer to check.
Put in order: AlphaGo, Dartmouth workshop, AlexNet, Deep Blue, the perceptron, the transformer.
Show answer
Dartmouth (1956), perceptron (1958), Deep Blue (1997), AlexNet (2012), AlphaGo (2016), transformer (2017).
What two problems caused the first AI winter?
Show answer
Methods that worked on toy problems failed at real scale (combinatorial explosion and the sheer amount of knowledge needed), and the limits of single-layer perceptrons dimmed interest in neural networks; reports such as Lighthill's led to funding cuts.
Why did expert systems prove hard to maintain?
Show answer
Every new situation needed new rules written by hand, rules interacted unexpectedly, and the systems could not learn or handle cases their builders had not anticipated.
A game has a branching factor of 10. How many positions are there at depth 6? At depth 12?
Show answer
10⁶ = 1 million; 10¹² = 1 trillion.
Name the three ingredients that came together for the deep learning breakthrough around 2012.
Show answer
Large labelled datasets (such as ImageNet), GPU computing, and improved training techniques for deep networks.
The winning ImageNet error fell from 16.4% in 2012 to 6.7% in 2014. What was the average yearly reduction factor?
Show answer
(6.7/16.4)^(1/2) = 0.64, so errors fell by about 36% per year on average.
If training cost grows 3.5× per year, how much more does a frontier training run cost after 3 years?
Show answer
3.5³ ≈ 43 times.
What did the transformer change compared with earlier sequence models?
Show answer
Attention lets every position draw directly on every other, and the architecture trains efficiently in parallel on GPUs, so it scales to very large models and datasets.
State "the bitter lesson" and give one example from this chapter that supports it.
Show answer
General methods that scale with computation tend to beat hand-crafted knowledge. Examples: deep networks beating hand-engineered vision features on ImageNet; AlphaGo learning Go strategy rather than being given expert rules.
Name Canada's three national AI institutes and their cities.
Show answer
Amii (Edmonton), Mila (Montréal) and the Vector Institute (Toronto).
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.